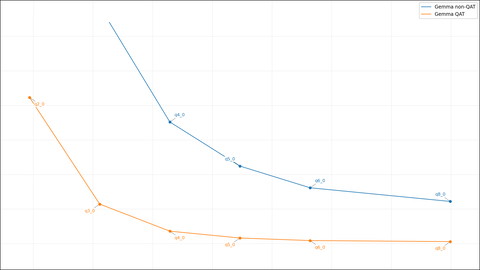
Does QAT make Gemma 4 31B usable with a quantized KV cache? Standard tail-free cache answers first, with Precision Tail and KVarN results as secondary checks.
413 cache configurations benchmarked with KLD across Qwen 3.6 27B and Gemma 4 31B, turned into a recommendation ladder from high end to extreme compression.
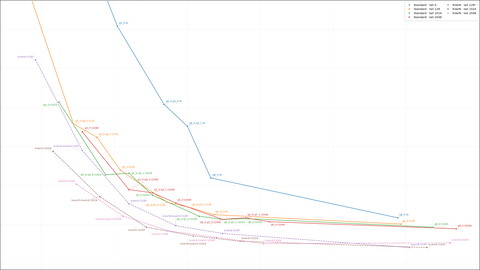
A small exact recent tail can recover much of a low-bit KV cache's lost precision, as shown on Qwen 3.6 27B and Gemma 4 31B across standard and KVarN formats.

KVarN, a Variance-Normalized KV-Cache Quantization from Huawei, improves KLD vs standard llama.cpp quants at every tested width on Qwen 3.6 27B and Gemma 4 31B.

Tests on Qwen 3.6 27B show why TurboQuant is overrated but saved by TCQ, q5 deserves more attention, and symmetric q8 might be a waste of VRAM.

How I built 3 massive AI mods for Paradox grand strategy games (Stellaris, Victoria 3, Imperator: Rome) in a scripting language that doesn't even have arrays.

Advanced AI game rule, road building system, fort placement optimization, and a comprehensive overview of all AI improvements.

Mercenary recruitment, governor policy rework, research efficiency-based building decisions, and economic policy improvements using the new modifier: syntax.

Added law management, tribal reform, diplomatic stances, state investment, character loyalty, and economic policy improvements.

Reworked AI decision making for buildings and inventions, introduced the Invention Relative Chance system, and improved city founding logic.

 Anbeeld
